Your AI Is Reading a Photocopy of a Photocopy
September 3, 2026 · Alex Weeks · AI & Automation, Title Industry
The July 7 post argued that an AI title workflow is only as good as the index underneath it. This one goes a layer further down, to the layer I have never once seen a title company audit: the images themselves.
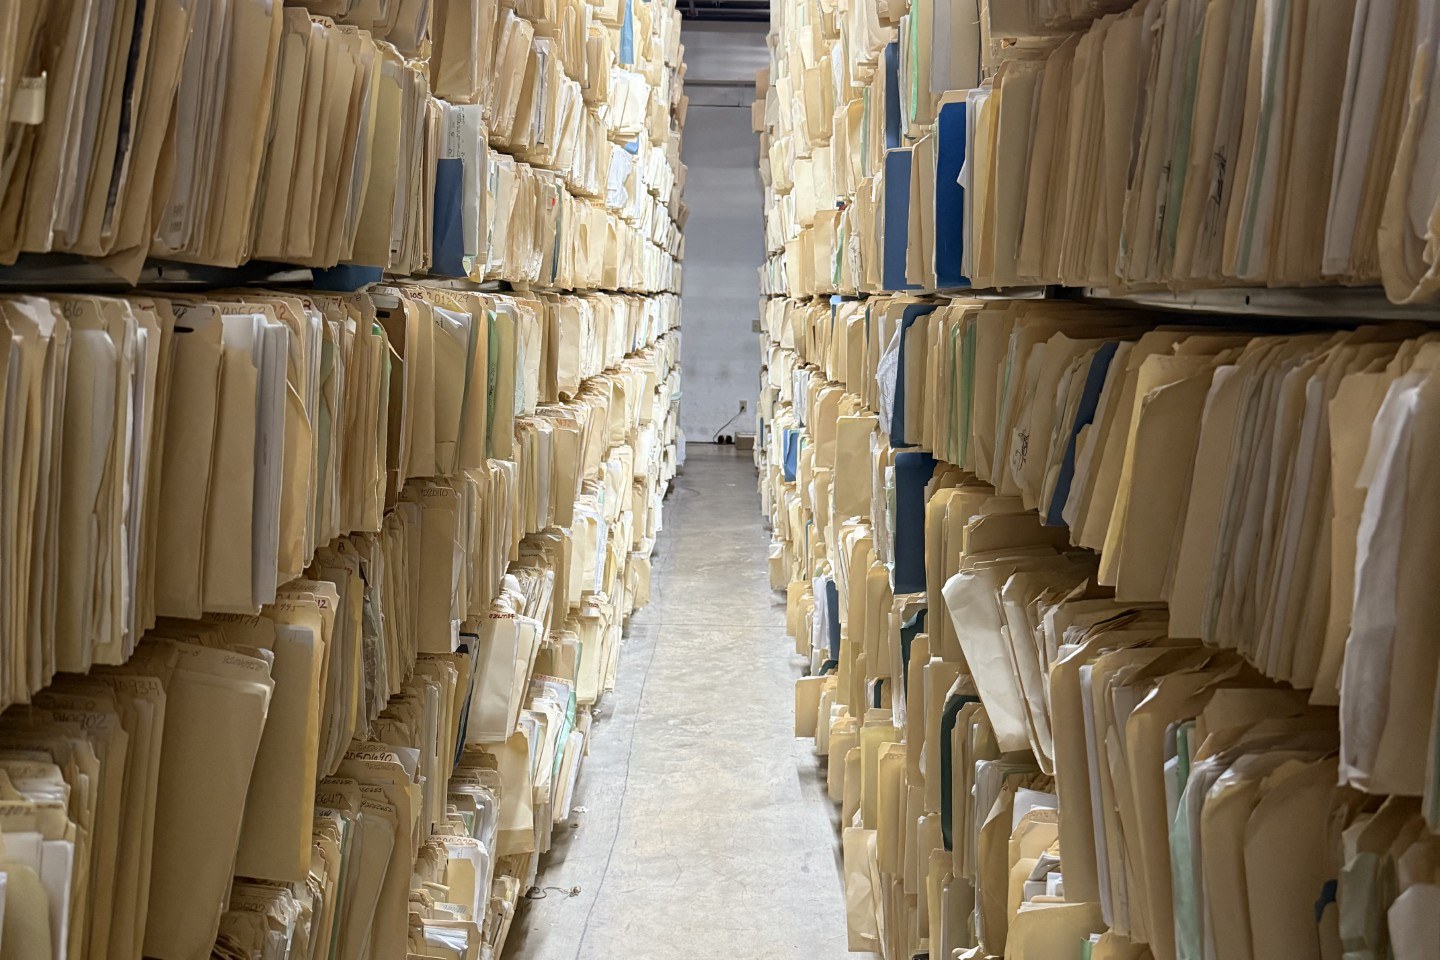
Every extraction pipeline — ours included — starts with a picture of a document. Not the document. A picture of it. And in this industry that picture has usually been through several lossy generations before any model sees it. A 1948 warranty deed was typed on onionskin, recorded, photographed onto microfilm in 1972, and scanned in 2004 by the low bidder on a county digitization contract, at whatever DPI the contract specified, which was the minimum. Your AI is not reading the deed. It’s reading a photocopy of a photocopy of a photocopy, and each generation threw away information no model can recover.
What Actually Degrades
Resolution first. Most county back-file scans were captured at 200 DPI because that was the archival floor when the contracts were written. At 200 DPI, the strokes that distinguish a handwritten 3 from a 5, or an 8 from a B, occupy a handful of pixels. Modern extraction wants 300 as a working minimum, and the difference isn’t cosmetic — it’s the difference between a character being present in the data and being genuinely ambiguous.
Then bit depth. A huge share of archival county imagery is bitonal — one bit per pixel, black or white, stored as Group 4 TIFF because it compressed well when storage was expensive. The black-or-white threshold was decided at scan time, decades ago, by whatever setting the operator used that day. Faint typewriter strikes fell below it and vanished. Stamp ink bled above it and became solid blobs. Grayscale would have preserved the ambiguity for a model to reason about. Bitonal resolved the ambiguity, permanently, and sometimes wrongly.
Microfilm adds its own layer: skew from film that wasn’t square in the camera, bleed-through where the back page ghosts into the front, frame-edge vignetting that darkens the margins — which is exactly where recording stamps, book-and-page cites, and marginal releases live. And under all of it, handwriting. Pre-1960s instruments in most counties are partly or fully handwritten, and handwriting recognition degrades faster with image quality than type does, because the model has fewer structural regularities to lean on.
The Cliff, Not the Slope
Here’s the part that matters if you’re buying extraction: accuracy does not decline gracefully as source quality drops. It falls off a cliff, for a compounding reason and a nastier one.
The compounding reason is arithmetic. A field is only correct if every character in it is correct. A book-and-page cite, a legal call, a grantor name — these are strings, and per-character accuracy compounds. At 99.5% per character, a 40-character legal call comes out clean about 82% of the time. Drop to 97% per character — very achievable on bad bitonal microfilm — and that field is right 30% of the time. A modest-sounding decline in character accuracy is a catastrophic decline in field accuracy, and fields are what you actually use.
The nastier reason is that modern models fail differently than the old OCR did. I spent years in the 2000s building n-gram correction for OCR of real estate documents, and the failures back then were loud — garbage characters you could catch with a dictionary. Large models fail confidently. When the pixels genuinely don’t contain enough information, a language model doesn’t emit noise; it emits the most plausible completion. A smeared grantor name becomes a clean, well-formatted, wrong grantor name. Below a certain image-quality threshold your error mode shifts from detectable to undetectable, and no downstream review catches an error that looks exactly like a correct answer. That shift is the thing to fear, and no vendor’s accuracy slide will show you where it happens.
Audit Your Capture Layer
This is checkable, and almost nobody checks it. Pull a random sample of a few hundred images from your back plant, stratified by decade. Measure four things: actual DPI (measured against known type sizes, not the number stamped in the file header), bit depth, skew, and the fraction of pages with visible bleed-through or frame damage. Then run your extraction on that stratified sample and score it by decade. Every shop I’ve watched do this discovers the same thing: the post-1990 accuracy numbers — the ones the vendor demoed — say nothing about the 1940–1975 band, where half the search risk lives.
If the images are bad, the fixes are unglamorous but real. Rescan targeted date ranges at higher quality where the county still holds the film. Prefer grayscale sources over bitonal wherever both exist. Route low-confidence extractions to a human by policy rather than by accident. What you should not do is average the problem away. A plant that’s 98% accurate overall and 70% accurate on pre-1970 handwritten instruments is not a 98% plant. It’s a 70% plant on exactly the documents where a miss becomes a claim.
Where I’ve Planted Our Flag
Scribe and Autopilot both live downstream of your images — Autopilot working the documents upstream, Scribe reading the instruments and drafting the report — so this problem is our problem, every day. We built both on the position that extraction from archival records should be verifiable, not taken on faith: the source image stays one click from everything read out of it, and a low-confidence read gets flagged and routed to a human by design instead of being smoothed into plausible text. I won’t claim we can conjure detail out of a 200 DPI bitonal scan; nobody can, and anyone who says otherwise is selling you the confident failure mode I just described. What I’ll claim is that when the source is marginal, the honest architecture admits it — and keeps a human’s eyes one click from the pixels.
Your model is only as good as the worst decade in your image archive. Go find out which decade that is.